How to manage a pool of machine learning models for crypto trading
How to use MLFlow to manage end to end machine learning workflows that will be used for crypto trading.
Github url: https://github.com/OrestisStefanou/CryptoTrading
Table of Contents
- Project Goal
- Solution
- Data Gathering
- Deployment Pipeline
- Batch Predictions
- Serve Predictions
- Putting it all together
Project Goal
The goal of the project is to be able to predict the price movement of the 20 most established cryptocurrencies in the next 10 days and more specifically if the 10 day moving average will be at least 5% higher(in this case we buy) or lower(in this case we sell) 10 days from the time of the prediction.
Solution
For each cryptocurrency we will have 2 binary classifiers.
- Downtrend classifier: This classifier will predict if the 10day moving average will be at least 5% lower in 10 days than the 10day moving average at the time of the prediction.
- Uptrend classifier: This classifier will predict if the 10day moving average will be at least 5% higher in 10 days than the 10day moving average at the time of the prediction.
In the next sections we will cover the following:
- Data gathering and feature engineering
- Deployment Pipeline
- Batch Predictions
- Prediction serving through a FastAPI web service
- Using MLFlow to automate the machine learning workflows
Data Gathering
The machine learning models will be trained with various technical indicators that we will get from Alpha Vantage(http://alphavantage.co/). The technical indicators were chosen mostly based on their popularity and are the ones below:
- OBV (on balance volume)
- AD (Chaikin A/D line)
- ADX (average directional movement index)
- AROON
- MACD (moving average convergence / divergence)
- RSI (relative strength index)
- STOCH (stochastic oscillator values)
- MFI (money flow index)
- DX (directional movement index)
- TRIX (1-day rate of change of a triple smooth exponential moving average )
- BBANDS (Bollinger bands)
- PPO (percentage price oscillator)
Below is the code that will be used to fetch the data from Alpha Vantage and to perform feature engineering to create new features from the features above.
import pandas as pd
import httpx

import settings


class DataGenerator:
    def __init__(self, symbol: str, fetch_data: bool = True) -> None:
        self.symbol = symbol
        if fetch_data:
            self.data = self._fetch_data()
        else:
            self.data = None

    def _get_techninal_indicator_daily_time_series(
        self,
        indicator: str,
        time_period: int = None
    ) -> pd.DataFrame:
        if time_period is None:
            time_period = settings.time_period

        params = {
            'apikey': settings.apikey,
            'symbol': f"{self.symbol}USDT",
            'function': indicator,
            'interval': settings.interval,
        }

        if indicator == 'AD':
            indicator = 'Chaikin A/D'

        if indicator in ['SMA', 'WMA', 'RSI', 'BBANDS', 'TRIX']:
            params['time_period'] = time_period
            params['series_type'] = settings.series_type

        if indicator in ['DX', 'MFI', 'AROON', 'ADX']:
            params['time_period'] = time_period

        if indicator in ['MACD', 'PPO']:
            params['series_type'] = settings.series_type

        json_response = httpx.get(
            url='https://www.alphavantage.co/query',
            params=params
        ).json()
        time_series = []

        for date, data in json_response[f"Technical Analysis: {indicator}"].items():
            if indicator == 'STOCH':
                time_series.append(
                {
                    "date": date,
                    "SlowK": float(data["SlowK"]),
                    "SlowD": float(data["SlowD"])
                }
            )
            elif indicator == 'AROON':
                time_series.append(
                {
                    "date": date,
                    "AroonDown": float(data["Aroon Down"]),
                    "AroonUp": float(data["Aroon Up"])
                }
            )
            elif indicator == 'MACD':
                time_series.append(
                {
                    "date": date,
                    "MACD": float(data["MACD"]),
                    "MACD_Signal": float(data["MACD_Signal"]),
                    "MACD_Hist": float(data["MACD_Hist"]),
                }
            )
            elif indicator == 'BBANDS':
                time_series.append(
                {
                    "date": date,
                    "Real_Upper_Band": float(data["Real Upper Band"]),
                    "Real_Lower_Band": float(data["Real Lower Band"])
                }
                )
            else:
                if "time_period" in params:
                    indicator_name = f"{time_period}_day_{indicator}"
                else:
                    indicator_name = indicator
                time_series.append(
                    {
                        "date": date,
                        indicator_name: float(data[indicator])
                    }
                )

        return pd.DataFrame(time_series)

    def _get_crypto_daily_time_series(self, market: str = 'USD') -> pd.DataFrame:
        json_response = httpx.get(f'https://www.alphavantage.co/query?function=DIGITAL_CURRENCY_DAILY&symbol={self.symbol}&market={market}&apikey={settings.apikey}').json()
        time_series = []

        for date, data in json_response["Time Series (Digital Currency Daily)"].items():
            time_series.append(
                {
                    "date": date,
                    "open": float(data["1. open"]),
                    "high": float(data["2. high"]),
                    "low": float(data["3. low"]),
                    "close": float(data["4. close"]),
                    "volume": float(data["5. volume"]),
                }
            )

        return pd.DataFrame(time_series)

    def _transform_data(self, data: pd.DataFrame) -> pd.DataFrame:
        data['OBV_pct_change'] = data['OBV'].pct_change() * 100
        data['AD_pct_change'] = data['Chaikin A/D'].pct_change() * 100
        data['7_day_TRIX'] = data['7_day_TRIX'] * 100
        data['BBANDS_distance_pct'] = ((data['Real_Upper_Band'] - data['Real_Lower_Band']) / data['Real_Lower_Band']) * 100
        data['2_day_SMA_10_day_SMA_pct_diff'] = ((data['2_day_SMA'] - data['10_day_SMA']) / data['10_day_SMA']) * 100
        data['2_day_SMA_20_day_SMA_pct_diff'] = ((data['2_day_SMA'] - data['20_day_SMA']) / data['20_day_SMA']) * 100
        data['10_day_SMA_20_day_SMA_pct_diff'] = ((data['10_day_SMA'] - data['20_day_SMA']) / data['20_day_SMA']) * 100
        data.drop(columns=['OBV', 'Chaikin A/D', 'Real_Upper_Band', 'Real_Lower_Band', '2_day_SMA', '10_day_SMA', '20_day_SMA', 'date'], axis=1, inplace=True)
        data.dropna(inplace=True)
        columns_to_convert = data.columns[data.columns != 'target']
        data[columns_to_convert] = data[columns_to_convert].astype(float)
        return data

    def _fetch_data(self) -> pd.DataFrame:
        time_series_df = self._get_techninal_indicator_daily_time_series(
            indicator="SMA",
            time_period=10
        )

        indicators_dfs = []
        indicators_dfs.append(self._get_techninal_indicator_daily_time_series(indicator="SMA", time_period=2))
        indicators_dfs.append(self._get_techninal_indicator_daily_time_series(indicator="SMA", time_period=20))
        for indicator in settings.indicators:
            indicators_dfs.append(self._get_techninal_indicator_daily_time_series(indicator))

        merged_df = pd.merge(time_series_df, indicators_dfs[0], on='date')
        for df in indicators_dfs[1:]:
            merged_df = pd.merge(merged_df, df, on='date')

        merged_df['date'] = pd.to_datetime(merged_df['date'])
        merged_df.sort_values(by='date', inplace=True)
        merged_df.reset_index(inplace=True, drop=True)
        return merged_df

    def get_dataset(
        self,
        look_ahead_days: int = settings.prediction_window_days,
        downtrend: bool = False
    ) -> pd.DataFrame:
        """
        Returns the dataset that will be user for training and evaluation of the models
        Params:
        - look_ahead_days: the prediction timeframe
        - downtrend: If True the target variable will contain 1 if the price will go down,
        If False the target variable will contain 1 if the price will go up
        """
        if self.data is None:
            data = self._fetch_data()
        else:
            data = self.data.copy()

        # Creata a new column with the target variable
        data['future_SMA'] = data['10_day_SMA'].shift(-look_ahead_days)
        data.dropna(inplace=True)
        percentage_difference = (data['future_SMA'] - data['10_day_SMA']) / data['10_day_SMA']
        if downtrend:
            data['target'] = (percentage_difference <= settings.target_downtrend_pct).astype(int)
        else:
            data['target'] = (percentage_difference >= settings.target_uptrend_pct).astype(int)

        data.drop(columns=['future_SMA',], axis=1, inplace=True)
        data = self._transform_data(data)
        data.dropna(inplace=True)

        return data

    def get_prediction_input(self, number_of_instances: int = 1) -> pd.DataFrame:
        if self.data is None:
            data = self._fetch_data()
        else:
            data = self.data.copy()

        data = self._transform_data(data)
        return data.tail(number_of_instances)
Deployment Pipeline
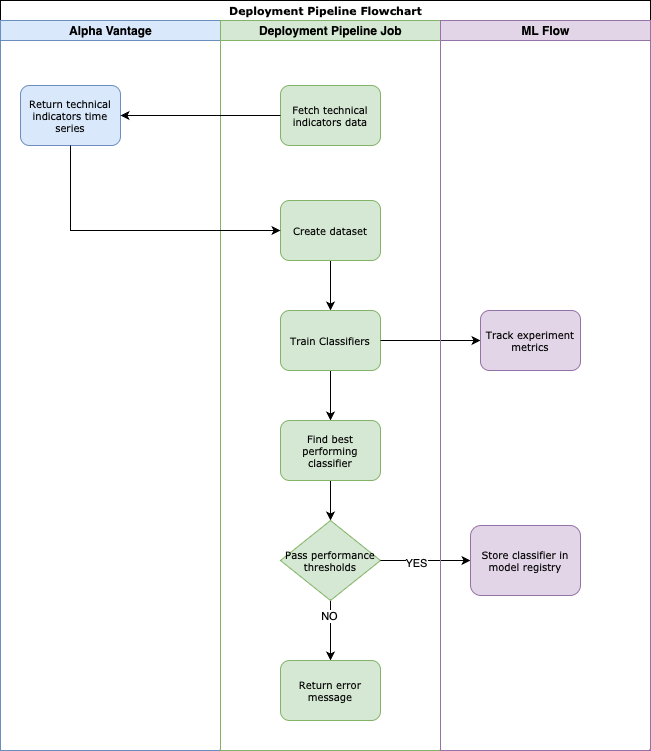
The deployment pipeline will take as parameters the symbol of the cryptocurrency and the trend type(uptrend/downtrend). The pipeline is broken down into three tasks
- Split the dataset into train and test set.
- Train various machine learning models.
- Find best performing model and if it passes the performance thresholds store it in model registry.
We will use MLFlow for experiment tracking and model deployment. A very high level of the deployment pipeline flow is shown in the flowchart below
Utility Functions
First we create some utility functions that we will use in the deployment pipeline.
deployment/utis.py
import pandas as pd
from sklearn.metrics import accuracy_score, confusion_matrix
from sklearn.metrics import precision_score
from sklearn.linear_model import RidgeClassifier


def split_dataset(dataset: pd.DataFrame, training_pct: float = 0.95) -> tuple[pd.DataFrame, pd.DataFrame]:
    n = len(dataset)
    train_dataset = dataset[0:int(n*training_pct)]
    test_dataset = dataset[int(n*training_pct):]

    return train_dataset, test_dataset


def get_overall_score(accuracy: float, precision: float, negative_accuracy: float, positive_accuracy: float) -> float:
    return (0.1 * accuracy) + (0.4 * precision) + (0.2 * negative_accuracy) + (0.3 * positive_accuracy)


def evaluate_classifier(
    classifier: object,
    X_train: pd.DataFrame,
    y_train: pd.DataFrame,
    X_test: pd.DataFrame,
    y_test: pd.DataFrame,
    threshold: float = 0.5
):
    """
    Returns a dictionary with the following metrics:
    - accuracy
    - precision
    - positive_accuracy
    - negative_accuracy
    - true_negatives
    - true_positives
    - false_positives
    - false_negatives
    - overall_score
    """
    classifier.fit(X_train, y_train)
    labels =  classifier.classes_
    if labels[0] != 0:
        raise Exception("Labels order is not the expected one")

    if not isinstance(classifier, RidgeClassifier):
      y_prob = classifier.predict_proba(X_test)
      y_pred = [
          1 if prediction_prob[1] > threshold else 0
          for prediction_prob in y_prob
      ]
    else:
      y_pred = classifier.predict(X_test)

    cm = confusion_matrix(y_test, y_pred, labels=[0,1])
    accuracy = accuracy_score(y_test, y_pred)
    precision = precision_score(y_test, y_pred)
    negative_accuracy = cm[0][0] / (cm[0][0] + cm[0][1])
    positive_accuracy = cm[1][1] / (cm[1][0] + cm[1][1])
    return {
        "accuracy": accuracy,
        "precision": precision,
        "positive_accuracy": positive_accuracy,
        "negative_accuracy": negative_accuracy,
        "true_negatives": cm[0][0],
        "true_positives": cm[1][1],
        "false_positives": cm[0][1],
        "false_negatives": cm[1][0],
        "overall_score": get_overall_score(accuracy, precision, negative_accuracy, positive_accuracy)
    }
Neural Net
Then we define a wrapper class on top of tensorflow so that all the machine learning models we use have the same api.
import pandas as pd
import tensorflow as tf

class NeuralNet:
    """
    A wrapper class on top of tensorflow
    """
    def __init__(
        self,
        class_weight: dict[str, float] = None,
        model: tf.keras.Sequential = None,
        normalizer: tf.keras.layers.Normalization = None
    ) -> None:
        self._class_weight = class_weight
        self.classes_ = [0, 1]
        self._model = model
        self._normalizer = normalizer

    def fit(self, X_train: pd.DataFrame, y_train: pd.DataFrame) -> None:
        self._normalizer = tf.keras.layers.Normalization()
        self._normalizer.adapt(X_train.to_numpy())

        # Build the neural network
        self._model = tf.keras.Sequential([
            self._normalizer,
            tf.keras.layers.Dense(64, activation='relu'),
            tf.keras.layers.Dense(64, activation='relu'),
            tf.keras.layers.Dense(1, activation='sigmoid')
        ])

        # Compile the model
        self._model.compile(
            optimizer='adam',
            loss='binary_crossentropy',
            metrics=['accuracy']
        )

        # Fit the model
        self._model.fit(X_train.to_numpy(), y_train.to_numpy(), epochs=100, class_weight=self._class_weight)

    def predict_proba(self, X_test: pd.DataFrame) -> list[list[float, float]]:
        """
        Returns the prediction probabilities in a list.
        At index 0 are the prediction probabilities for the zero class
        At index 1 are the prediction probabilities for the one class
        """
        y_pred_probs = self._model.predict(X_test.to_numpy())
        return [
            [1 - prob, prob] for prob in y_pred_probs
        ]

    def predict(self, X_test: pd.DataFrame) -> list[float]:
        return self._model.predict(X_test.to_numpy())

    def predict_flatten(self, X):
        return self._model.predict(X).flatten()
Deployment Pipeline Class
Now the deployment pipeline part where it all comes together. We start with all the necessary imports and the constructor.
import logging
import datetime as dt
from enum import Enum
from typing import Optional

import numpy as np
import pandas as pd
from sklearn.ensemble import RandomForestClassifier
from sklearn.ensemble import HistGradientBoostingClassifier, AdaBoostClassifier
from sklearn.linear_model import RidgeClassifier
from sklearn.neural_network import MLPClassifier
from sklearn.svm import SVC
from sklearn.neighbors import KNeighborsClassifier
from sklearn.utils.class_weight import compute_class_weight
import xgboost as xgb
from lightgbm import LGBMClassifier
import mlflow

import deployment.utils as utils
from model_registry.model_tags import ModelTags
from data.data_generator import DataGenerator
import settings
from deep_learning.neural_net import NeuralNet
from explainer.model_explainer import ModelExplainer

logging.basicConfig(level=logging.INFO)

class TrendType(Enum):
    UPTREND = 'uptrend'
    DOWNTREND = 'downtrend'

class DeploymentPipeline:
    def __init__(self, symbol: str, trend_type: TrendType) -> None:
        self.symbol = symbol
        self.trend_type = trend_type.value
        self._ml_flow_client = mlflow.MlflowClient(tracking_uri=settings.tracking_uri)
        mlflow.set_tracking_uri(settings.tracking_uri)
        mlflow.set_experiment(f"{symbol}_{trend_type.value}_{dt.datetime.now().isoformat()}")
        self._evaluation_results = {
            'Classifier': [],
            'Accuracy': [],
            'Precision': [],
            'Positive_Accuracy': [],
            'Negative_Accuracy': [],
            'Overall_Score': [],
            'Run_Id': []
        }
        self._classifier_artifact_path = f'{symbol}_{trend_type.value}_classifier'
        self._registered_model_name = f"{symbol}_{trend_type.value}_model"
        self._prediction_window_days = settings.prediction_window_days
        self._target_pct = settings.target_uptrend_pct if trend_type == TrendType.UPTREND else settings.target_downtrend_pct
        self.X_train = None
        self.X_test = None
        self.y_train = None
        self.y_test = None
Some things that are worth noting here are the MLFlow related lines of code
self._ml_flow_client = mlflow.MlflowClient(tracking_uri=settings.tracking_uri)
mlflow.set_tracking_uri(settings.tracking_uri)
mlflow.set_experiment(f"{symbol}_{trend_type.value}_{dt.datetime.now().isoformat()}")
We initialize the MLFlow client by passing the tracking_uri which is the url that the MLFlow server is running(locally in our case). Then we set the experiment name where we will then be able to see all the runs under this experiment(more on this later).
Train models
Next is the train models step
    def train_models(self) -> dict[str, object]:
        """
        This method trains the classifiers and stores the evaluation metrics in
        self._evaluation_results attribute.
        Returns:
        A dict with the name of the classifier and the trained model.
        Example:
        {
            "RandomForest": sklearn.ensemble.RandomForestClassifier,
            "XGBoost": xgb.XGBClassifier,
            "LightGBM": lightgbm.LGBMClassifier,
            "NeuralNet": deep_learning.neural_net.NeuralNet
        }
        """
        # Set the class weight dynamically using the distribution of y_train
        class_weights = self._calculate_class_weights(self.y_train)
        scale_pos_weight=self.y_train.value_counts()[0] / self.y_train.value_counts()[1]

        classifiers = self._get_classifiers(class_weights=class_weights, scale_pos_weight=scale_pos_weight)

        for clf_name, clf in classifiers.items():
            # Create a run under the experiment we created in the constructor
            with mlflow.start_run(run_name=f"{self.symbol}_{clf_name}") as run:
                metrics = utils.evaluate_classifier(clf, self.X_train, self.y_train, self.X_test, self.y_test)
                # Log the parameters for each classifier in MLFlow
                if isinstance(clf, xgb.XGBClassifier):
                    mlflow.log_params({"scale_pos_weight": scale_pos_weight})
                else:
                    mlflow.log_params({"class_weights": class_weights})

                # Log the performance metrics of the classifier in MLFlow
                mlflow.log_metrics(metrics)
                signature = mlflow.models.infer_signature(self.X_test, clf.predict(self.X_test))

                # Log the classifier in MLFlow
                if isinstance(clf, NeuralNet):
                    mlflow.tensorflow.log_model(
                        model=clf._model,
                        artifact_path=self._classifier_artifact_path
                    )
                else:
                    mlflow.sklearn.log_model(
                        sk_model=clf,
                        signature=signature,
                        artifact_path=self._classifier_artifact_path
                    )
            # Store the evaluation metrics to find the best performing model later
            self._store_evaluation_results(classifier_name=clf_name, metrics=metrics, run_id=run.info.run_id)

        return classifiers

    def _store_evaluation_results(self, classifier_name: str, metrics: dict[str, float], run_id: str) -> None:
        self._evaluation_results['Classifier'].append(classifier_name)
        self._evaluation_results['Accuracy'].append(metrics['accuracy'])
        self._evaluation_results['Precision'].append(metrics['precision'])
        self._evaluation_results['Positive_Accuracy'].append(metrics['positive_accuracy'])
        self._evaluation_results['Negative_Accuracy'].append(metrics['negative_accuracy'])
        self._evaluation_results['Overall_Score'].append(metrics['overall_score'])
        self._evaluation_results['Run_Id'].append(run_id)

    def _get_classifiers(self, class_weights: dict[str, float], scale_pos_weight: float = None) -> dict[str, object]:
        return {
            "RandomForest": RandomForestClassifier(class_weight=class_weights),
            "SupportVectorMachine": SVC(probability=True, class_weight=class_weights),
            "XGBoost": xgb.XGBClassifier(scale_pos_weight=scale_pos_weight),
            "HistGradientBoostingClassifier": HistGradientBoostingClassifier(class_weight=class_weights),
            "AdaBoostClassifier": AdaBoostClassifier(algorithm='SAMME'),
            "RidgeClassifier": RidgeClassifier(class_weight=class_weights),
            "KNeighborsClassifier": KNeighborsClassifier(),
            "MLPClassifier": MLPClassifier(),
            "LightGBM": LGBMClassifier(class_weight=class_weights),
            "NeuralNet": NeuralNet(class_weight=class_weights)
        }
A few things are happening here:
- Calculate the class weights dynamically from the distribution of y_train for better model performance
- For each classifier
- Create a new run under the experiment to track later in MLFlow
- Fit the model and get it’s performance metrics
- Log the model parameters that we used
- Log the performance metrics in MLFlow
- Log the model in MLFlow
- Store the performance metrics in self._evaluation_results to find the best performing model later
Register best performing model
Next up is the register best performing model step
    def register_best_performing_model(self, classifiers: dict[str, object]) -> Optional[mlflow.entities.model_registry.ModelVersion]:
        """
        Stores the best performing model in the model registry
        Returns the version of the deployed model or None
        in case that the best model failed to pass
        the performance thresholds.
        Params:
        - classifiers: A dict with the name of the classifier and the trained model
        """
        results_df = pd.DataFrame(self._evaluation_results)
        results_df.sort_values(by=['Overall_Score'], ascending=False, inplace=True)
        results_df.reset_index(inplace=True)
        run_id = results_df['Run_Id'][0]
        classifier_name = results_df['Classifier'][0]

        # Check if best performing model is passing the performance thresholds
        positive_accuracy = results_df['Positive_Accuracy'][0]
        negative_accuracy = results_df['Negative_Accuracy'][0]
        overall_score = results_df['Overall_Score'][0]
        accuracy = results_df['Accuracy'][0]
        precision = results_df['Precision'][0]

        if positive_accuracy > 0.5 and negative_accuracy > 0.5 and overall_score > 0.6:
            logging.info(f"Registering model for symbol: {self.symbol}")
            # URI that we the model is logged(see train models step)
            model_uri = f"runs:/{run_id}/{self._classifier_artifact_path}"
            feature_importance_dict = self._get_feature_importance(
                classifier=classifiers[classifier_name]
            )

            tags = ModelTags(
                positive_accuracy=positive_accuracy,
                negative_accuracy=negative_accuracy,
                overall_score=overall_score,
                accuracy=accuracy,
                precision=precision,
                symbol=self.symbol,
                classifier=classifier_name,
                classified_trend=self.trend_type,
                target_pct=self._target_pct,
                prediction_window_days=self._prediction_window_days,
                feature_names=list(self.X_train.columns),
                feature_importance=feature_importance_dict
            )
            # Add model in MLFlow model registry
            model_version = mlflow.register_model(model_uri=model_uri, name=self._registered_model_name, tags=tags.to_dict())
            return model_version
        else:
            logging.info(f"Model for {self.symbol} failed thresholds")
            return None

    def _get_feature_importance(
        self,
        classifier: object,
    ) -> dict[str, float]:
        """
        Returns the a dict with the mean shap value of each feature
        """
        explainer = ModelExplainer(model=classifier, sample_data=self.X_train)
        return explainer.explain(self.X_test)
Things here are straightforward
- Find the classifier with the highest overall score by ordering self._evaluation_results dataframe
- Check if the classifier passes the performance thresholds that we set
- In case that it passes the thresholds
- Calculate the feature importance(more on this later)
- Create the model tags where we store useful information(feature importance, performance metrics etc.) that we will need
- Add the model in the model registry of MLFlow
- If the best performing model doesn’t pass the thresholds just log an info message
Feature importance
Now to the feature importance part. Since we train a lot of different machine learning models and each one has a different way of calculating the feature importance we need a generic solution that can work for any algorithm. For this reason we use the shap values and more specifically the KernelExplainer and the TreeExplainer(for more info about this have a look here https://shap.readthedocs.io/en/latest/index.html)
import pandas as pd
import numpy as np
import shap
from xgboost import XGBClassifier
from lightgbm import LGBMClassifier

from deep_learning.neural_net import NeuralNet


class ModelExplainer:
    def __init__(self, model: object, sample_data: pd.DataFrame) -> None:
        self.model = model
        self._explainer = self._create_explainer(model, sample_data)

    def _create_explainer(self, classifier: object, X: pd.DataFrame) -> shap.Explainer:
        if isinstance(classifier, NeuralNet):
            return shap.KernelExplainer(
                model=classifier.predict_flatten,
                data=shap.utils.sample(X, 200),
                feature_names=list(X.columns)
            )

        if isinstance(classifier, XGBClassifier) or isinstance(classifier, LGBMClassifier):
            return shap.explainers.TreeExplainer(classifier)

        return shap.explainers.KernelExplainer(
            model=classifier.predict,
            data=shap.utils.sample(X, 200),
            feature_names=list(X.columns)
        )

    def explain(self, X: pd.DataFrame) -> dict[str, float]:
        """
        Returns the a dict with the mean shap value of each feature
        """
        feature_importance_dict = dict()
        shap_values = self._explainer.shap_values(X)
        mean_shap_values = np.mean(shap_values, axis=0)
        for index, feature_name in enumerate(list(X.columns)):
            feature_importance_dict[feature_name] = mean_shap_values[index]

        return feature_importance_dict
And lastly the run method
    def run(self):
        self.create_train_test_sets()
        classifiers = self.train_models()
        self.register_best_performing_model(classifiers)
Batch Predictions
A high level flowchart of batch predictions.
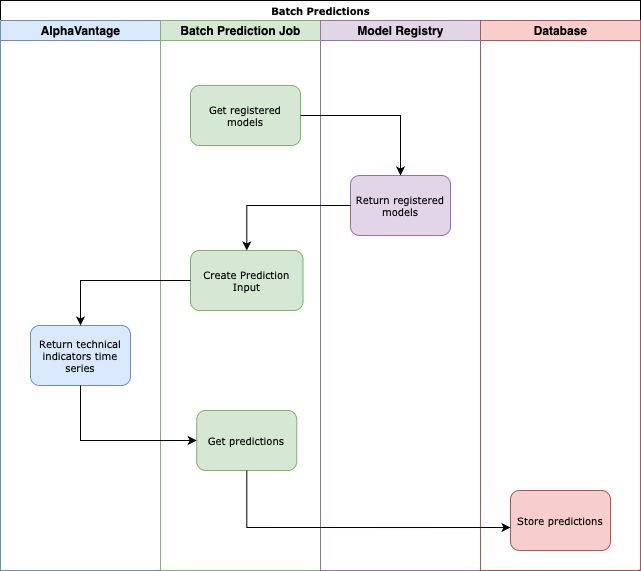
We start by defining the ModelRegistry and DeployedModel classes which are an abstraction on top of MLFlow model registry and registered model.
Deployed Model Class
import mlflow
from mlflow.entities.model_registry import RegisteredModel
import pandas as pd

from database.db import Database
from deployment.deployment_pipeline import TrendType
from deep_learning.neural_net import NeuralNet
from model_registry.model_tags import ModelTags
import settings

class DeployedModel:
    def __init__(self, model: RegisteredModel) -> None:
        self.model_name = model.name
        self.model_version = model.latest_versions[0].version
        self.tags: ModelTags = ModelTags(**model.latest_versions[0].tags)
        self.classified_trend = self.tags.classified_trend
        self.symbol = self.tags.symbol
        self.classifier_name = self.tags.classifier

        model_uri = f'models:/{self.model_name}/{self.model_version}'
        if self.classifier_name == 'NeuralNet':
            self.model = NeuralNet(
                model=mlflow.tensorflow.load_model(model_uri=model_uri)
            )
        else:
            self.model = mlflow.sklearn.load_model(model_uri=model_uri)

    def predict(self, model_input: pd.DataFrame, store_in_db: bool = True) -> float:
        """
        Returns the prediction probabilities for the positive class

        Params:
        - model_input: The input that the deployed model expects
        """
        if self.classifier_name == 'RidgeClassifier':
            prediction =  self.model.predict(model_input)[0]
        else:
            prediction =  self.model.predict_proba(model_input)[0][1]

        if store_in_db:
            self._store_predictions(prediction_prob=float(prediction), model_input=model_input.to_dict('records'))

        return prediction

    def _store_predictions(self, prediction_prob: float, model_input: dict) -> None:
        target_pct = self.tags.target_pct
        if target_pct is None:
            if self.classified_trend == TrendType.UPTREND.value:
                target_pct = settings.target_uptrend_pct
            else:
                target_pct = settings.target_downtrend_pct

        prediction_window_days = self.tags.prediction_window_days
        if prediction_window_days is None:
            prediction_window_days = settings.prediction_window_days

        Database().store_predictions(
            symbol=self.symbol,
            model_name=self.model_name,
            model_version=self.model_version,
            prediction_prob=prediction_prob,
            prediction_input=model_input,
            target_pct=target_pct,
            prediction_window_days=prediction_window_days
        )
Model Registry Class
import mlflow

import settings
from model_registry.deployed_model import DeployedModel
from deployment.deployment_pipeline import TrendType


class ModelRegistry:
    def __init__(self) -> None:
        self.mlflow_client = mlflow.MlflowClient(tracking_uri=settings.tracking_uri)
        mlflow.set_tracking_uri(settings.tracking_uri)

    def get_deployed_models(
        self,
        trend_type: TrendType = None,
        symbols: list[str] = None
    ) -> list[DeployedModel]:
        deployed_models = []

        for model in self.mlflow_client.search_registered_models():
            deployed_model = DeployedModel(model)

            if symbols and deployed_model.symbol not in symbols:
                continue

            if trend_type and deployed_model.classified_trend != trend_type.value:
                continue

            deployed_models.append(deployed_model)

        return deployed_models
Batch Predict Class
from dataclasses import dataclass
import time

import mlflow

from data.data_generator import DataGenerator
from deployment.deployment_pipeline import TrendType
from model_registry.model_tags import ModelTags
from model_registry.model_registry import ModelRegistry
import settings


@dataclass
class Prediction:
    symbol: str
    prediction: str
    tags: ModelTags


class BatchPredictions:
    def __init__(
        self,
        trend_type: TrendType,
        symbols: list[str] = None,
    ) -> None:
        self.trend_type = trend_type
        self.mlflow_client = mlflow.MlflowClient(tracking_uri=settings.tracking_uri)
        self.predictions: list[Prediction] = []
        self.symbols = symbols
        mlflow.set_tracking_uri(settings.tracking_uri)

    def run(self, store_in_db: bool = True) -> list[Prediction]:
        count = 0
        # Get all registered models
        model_registry = ModelRegistry()
        for deployed_model in model_registry.get_deployed_models(self.trend_type, self.symbols):
            prediction_input = DataGenerator(deployed_model.symbol).get_prediction_input()
            count += 1

            self.predictions.append(
                Prediction(
                    symbol=deployed_model.symbol,
                    prediction=deployed_model.predict(prediction_input, store_in_db),
                    tags=deployed_model.tags,
                )
            )

            if count == 5:
                time.sleep(65)  # Provider limitation
                count = 0

        return self.predictions
The class takes as optional parameters the trend_type and a list of symbols in case we want to narrow down the predictions. In case we don’t pass anything we will get predictions from all the models that are stored in the model registry.
Predictions serving
In case we want to expose our service to the outside world we need a way to serve our predictions to the public. To do that we will create a very simple fast api web service.
Schema
First we create the api schema
from pydantic import BaseModel

from deployment.deployment_pipeline import TrendType


class PerformanceMetrics(BaseModel):
    positive_accuracy: float
    negative_accuracy: float
    overall_score: float
    accuracy: float
    precision: float


class DeployedModel(BaseModel):
    symbol: str
    trend_type: TrendType
    feature_importance: dict[str, float]
    performance_metrics: PerformanceMetrics
    target_pct: float
    prediction_window_days: int


class Prediction(BaseModel):
    prediction_probabilities: float
    symbol: str
    trend_type: TrendType
Endpoints
Then we have to define the endpoints of our application. We will have two endpoints:
- List all models: This endpoint will return all the information of the models that we have stored in the model registry
- Get predictions endpoint: This endpoint will be used to give predictions to the users.It will take symbol and trend type as query parameters. The reason this endpoint returns predictions only for one model is time related. Because we create the prediction input on the fly(making requests to alpha vantage) it will take a lot of time to give predictions for a list of models. There are solutions for this(cache the prediction for a period of time or run batch predictions every 1 hour and store them) but to keep things simple we will keep it one prediction at a time.
import ast

from fastapi import FastAPI, HTTPException

from model_registry.model_registry import ModelRegistry
from deployment.deployment_pipeline import TrendType
from api import schema
from predictions.batch_predict import BatchPredictions

app = FastAPI()

@app.get("/models", status_code=200)
async def get_models() -> list[schema.DeployedModel]:
    deployed_models = ModelRegistry().get_deployed_models()
    return [
        schema.DeployedModel(
            symbol=model.symbol,
            trend_type=TrendType(model.classified_trend),
            # Convert string to dict
            feature_importance=ast.literal_eval(model.tags.feature_importance),
            target_pct=model.tags.target_pct,
            prediction_window_days=model.tags.prediction_window_days,
            performance_metrics=schema.PerformanceMetrics(
                positive_accuracy=model.tags.positive_accuracy,
                negative_accuracy=model.tags.negative_accuracy,
                overall_score=model.tags.overall_score,
                accuracy=model.tags.accuracy,
                precision=model.tags.precision
            )
        )
        for model in deployed_models
    ]


@app.get("/prediction", status_code=200)
async def get_prediction(symbol: str, trend_type: TrendType) -> schema.Prediction:
    batch_predictions = BatchPredictions(
        trend_type=trend_type,
        symbols=[symbol, ]
    ).run(store_in_db=False)

    if len(batch_predictions) == 0:
        raise HTTPException(status_code=404, detail=f"Model for symbol {symbol} and trend type {trend_type} not found.")

    return schema.Prediction(
        prediction_probabilities=batch_predictions[0].prediction,
        symbol=batch_predictions[0].symbol,
        trend_type=batch_predictions[0].tags.classified_trend
    )
Putting it all together
First we have to deploy some models. To do that we create a deploy models script that will take as command line argument the trend type and it for each cryptocurrency it will run the deployment pipeline.
import logging
import time
import warnings
import sys

import settings
from deployment.deployment_pipeline import DeploymentPipeline, TrendType

logging.basicConfig(level=logging.INFO)

# Filter out the specific warning
warnings.filterwarnings("ignore", category=UserWarning)


if __name__ == '__main__':
    count = 0
    trend_type = sys.argv[1]
    for crypto_symbol in settings.symbols:
        logging.info(f"Running deployment pipeline for {crypto_symbol}")
        try:
            pipeline = DeploymentPipeline(symbol=crypto_symbol, trend_type=TrendType(trend_type))
            pipeline.run()
            count += 1
        except Exception as e:
            logging.error(f"Error running deployment pipeline for {crypto_symbol}: {e}")

        if count == 5:
            time.sleep(65)  # Provider requests limitation is 30 requests per minute
            count = 0
First we have to start the MLFlow server
mlflow server --host 127.0.0.1 --port 8080
Then we run the deploy models script with uptrend as command line argument
python -m deployment.deploy_models uptrend
Experiment tracking
It’s time to see power of experiment tracking with MLFlow. By visiting http://127.0.0.1:8080 on our browser can see our experiments
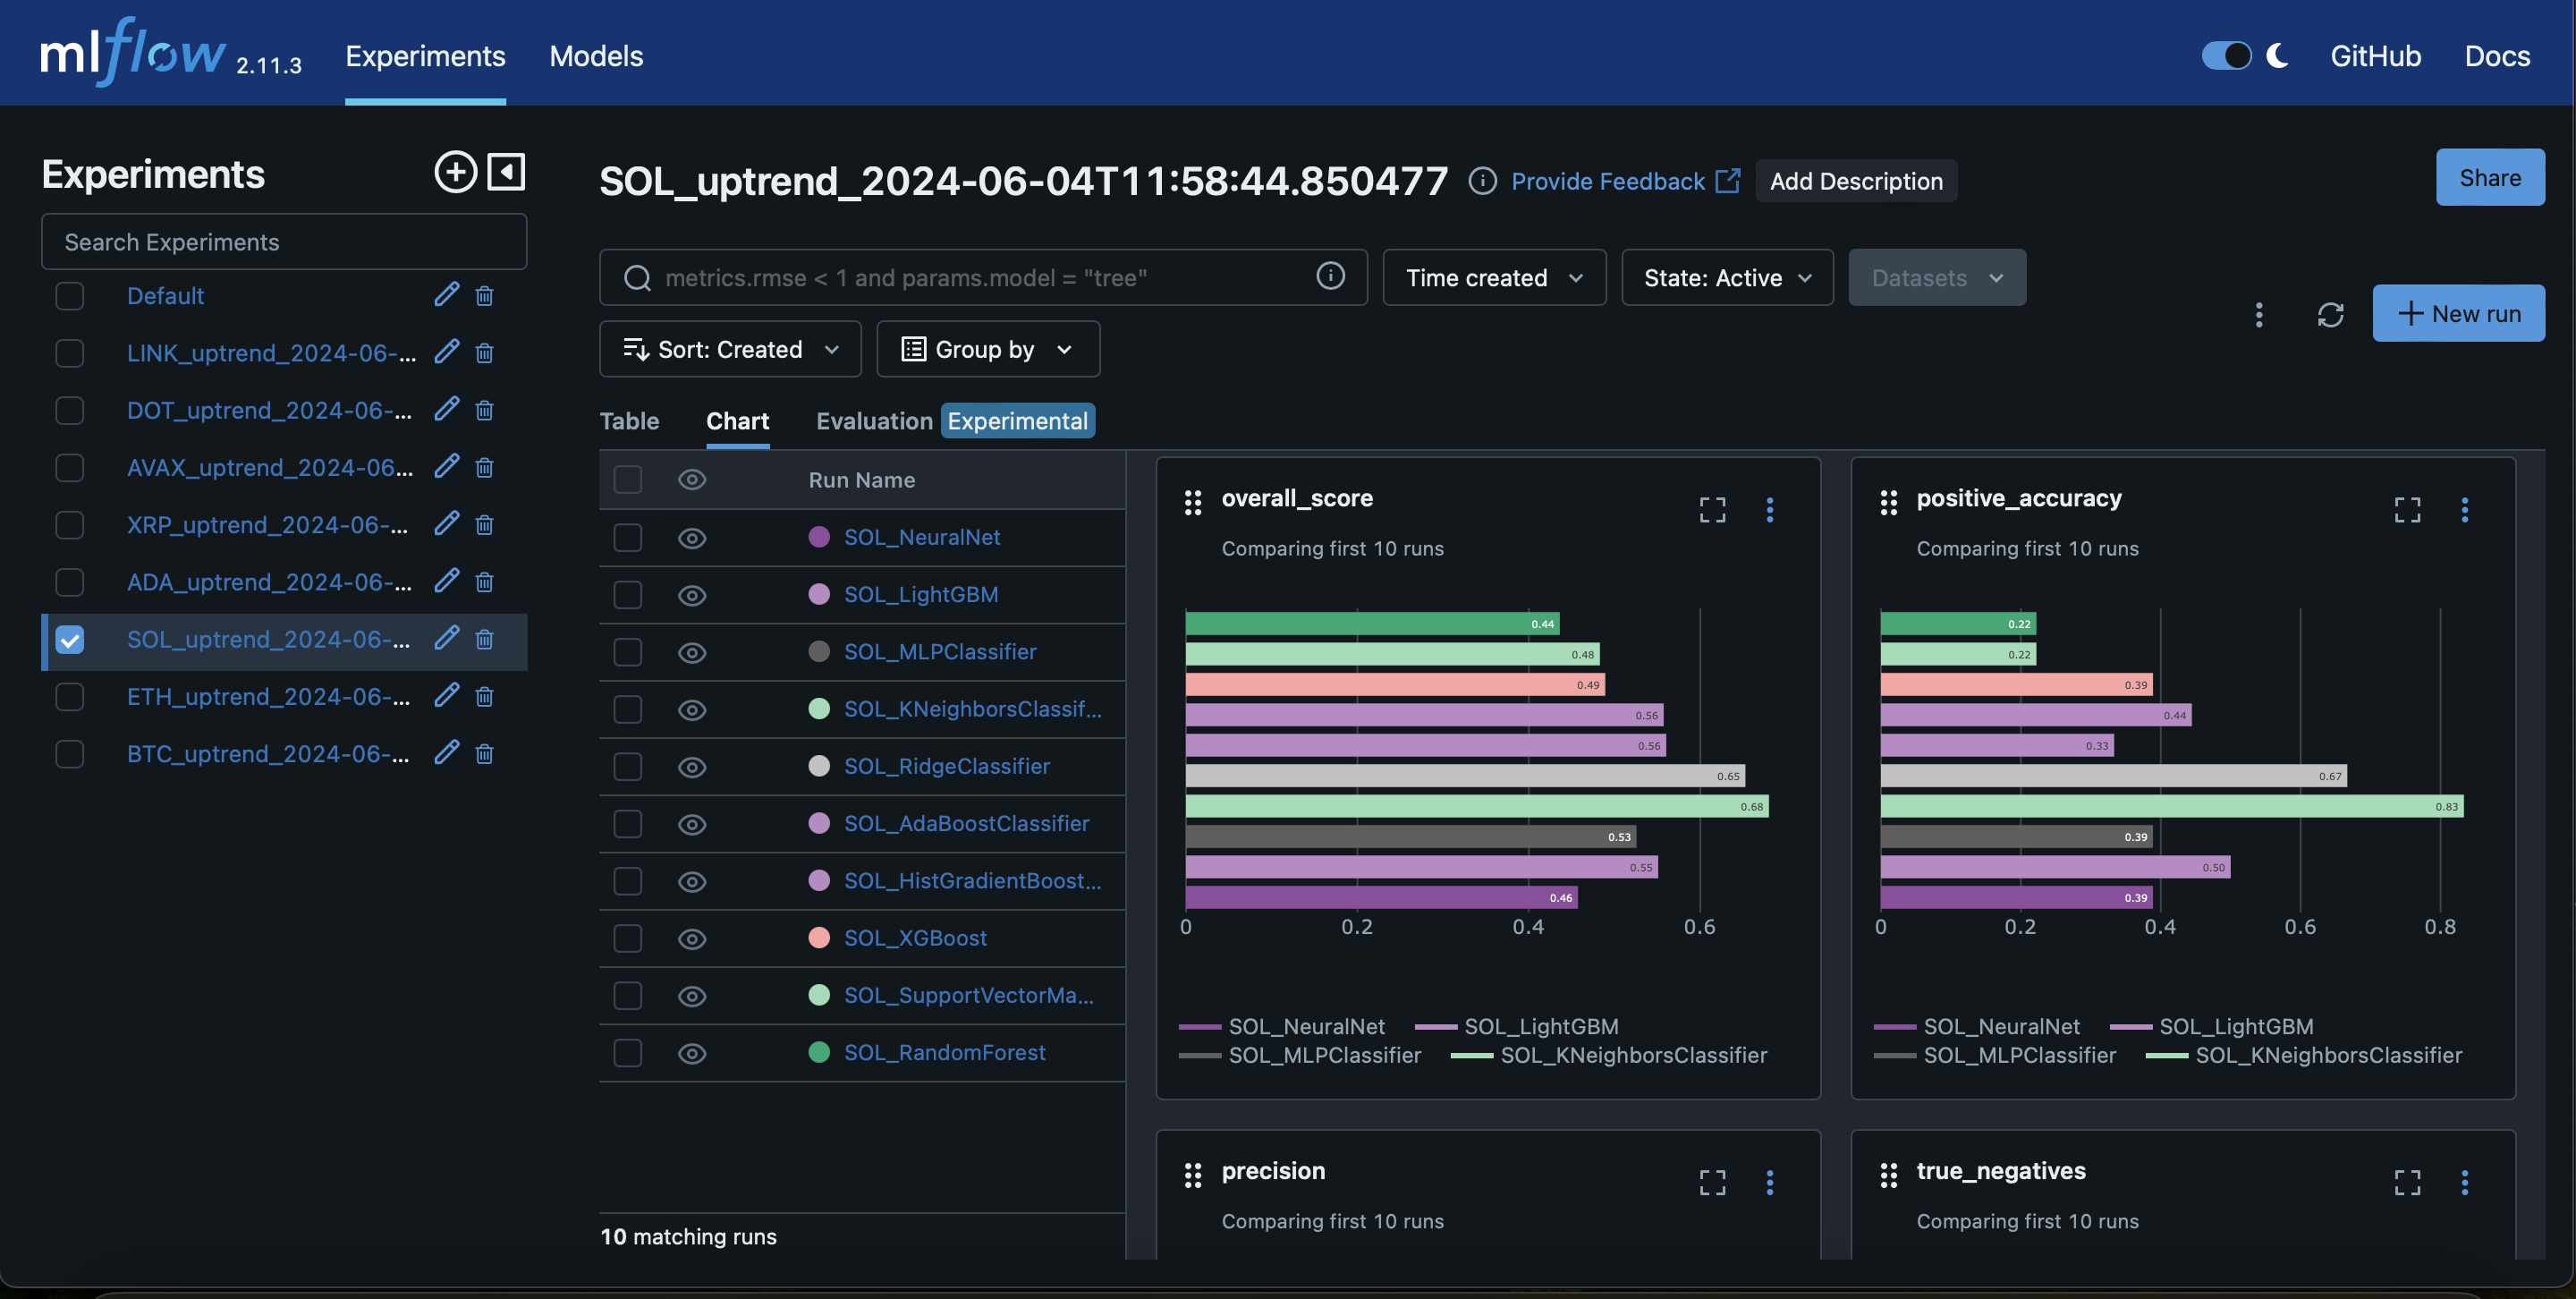
We can see that we have one experiment per symbol and by choosing one of them we can see the runs of the experiment. In our case we have one run per algorithm we tried and we can see that we have charts that show the performance metrics that we tracked for each algorithm.
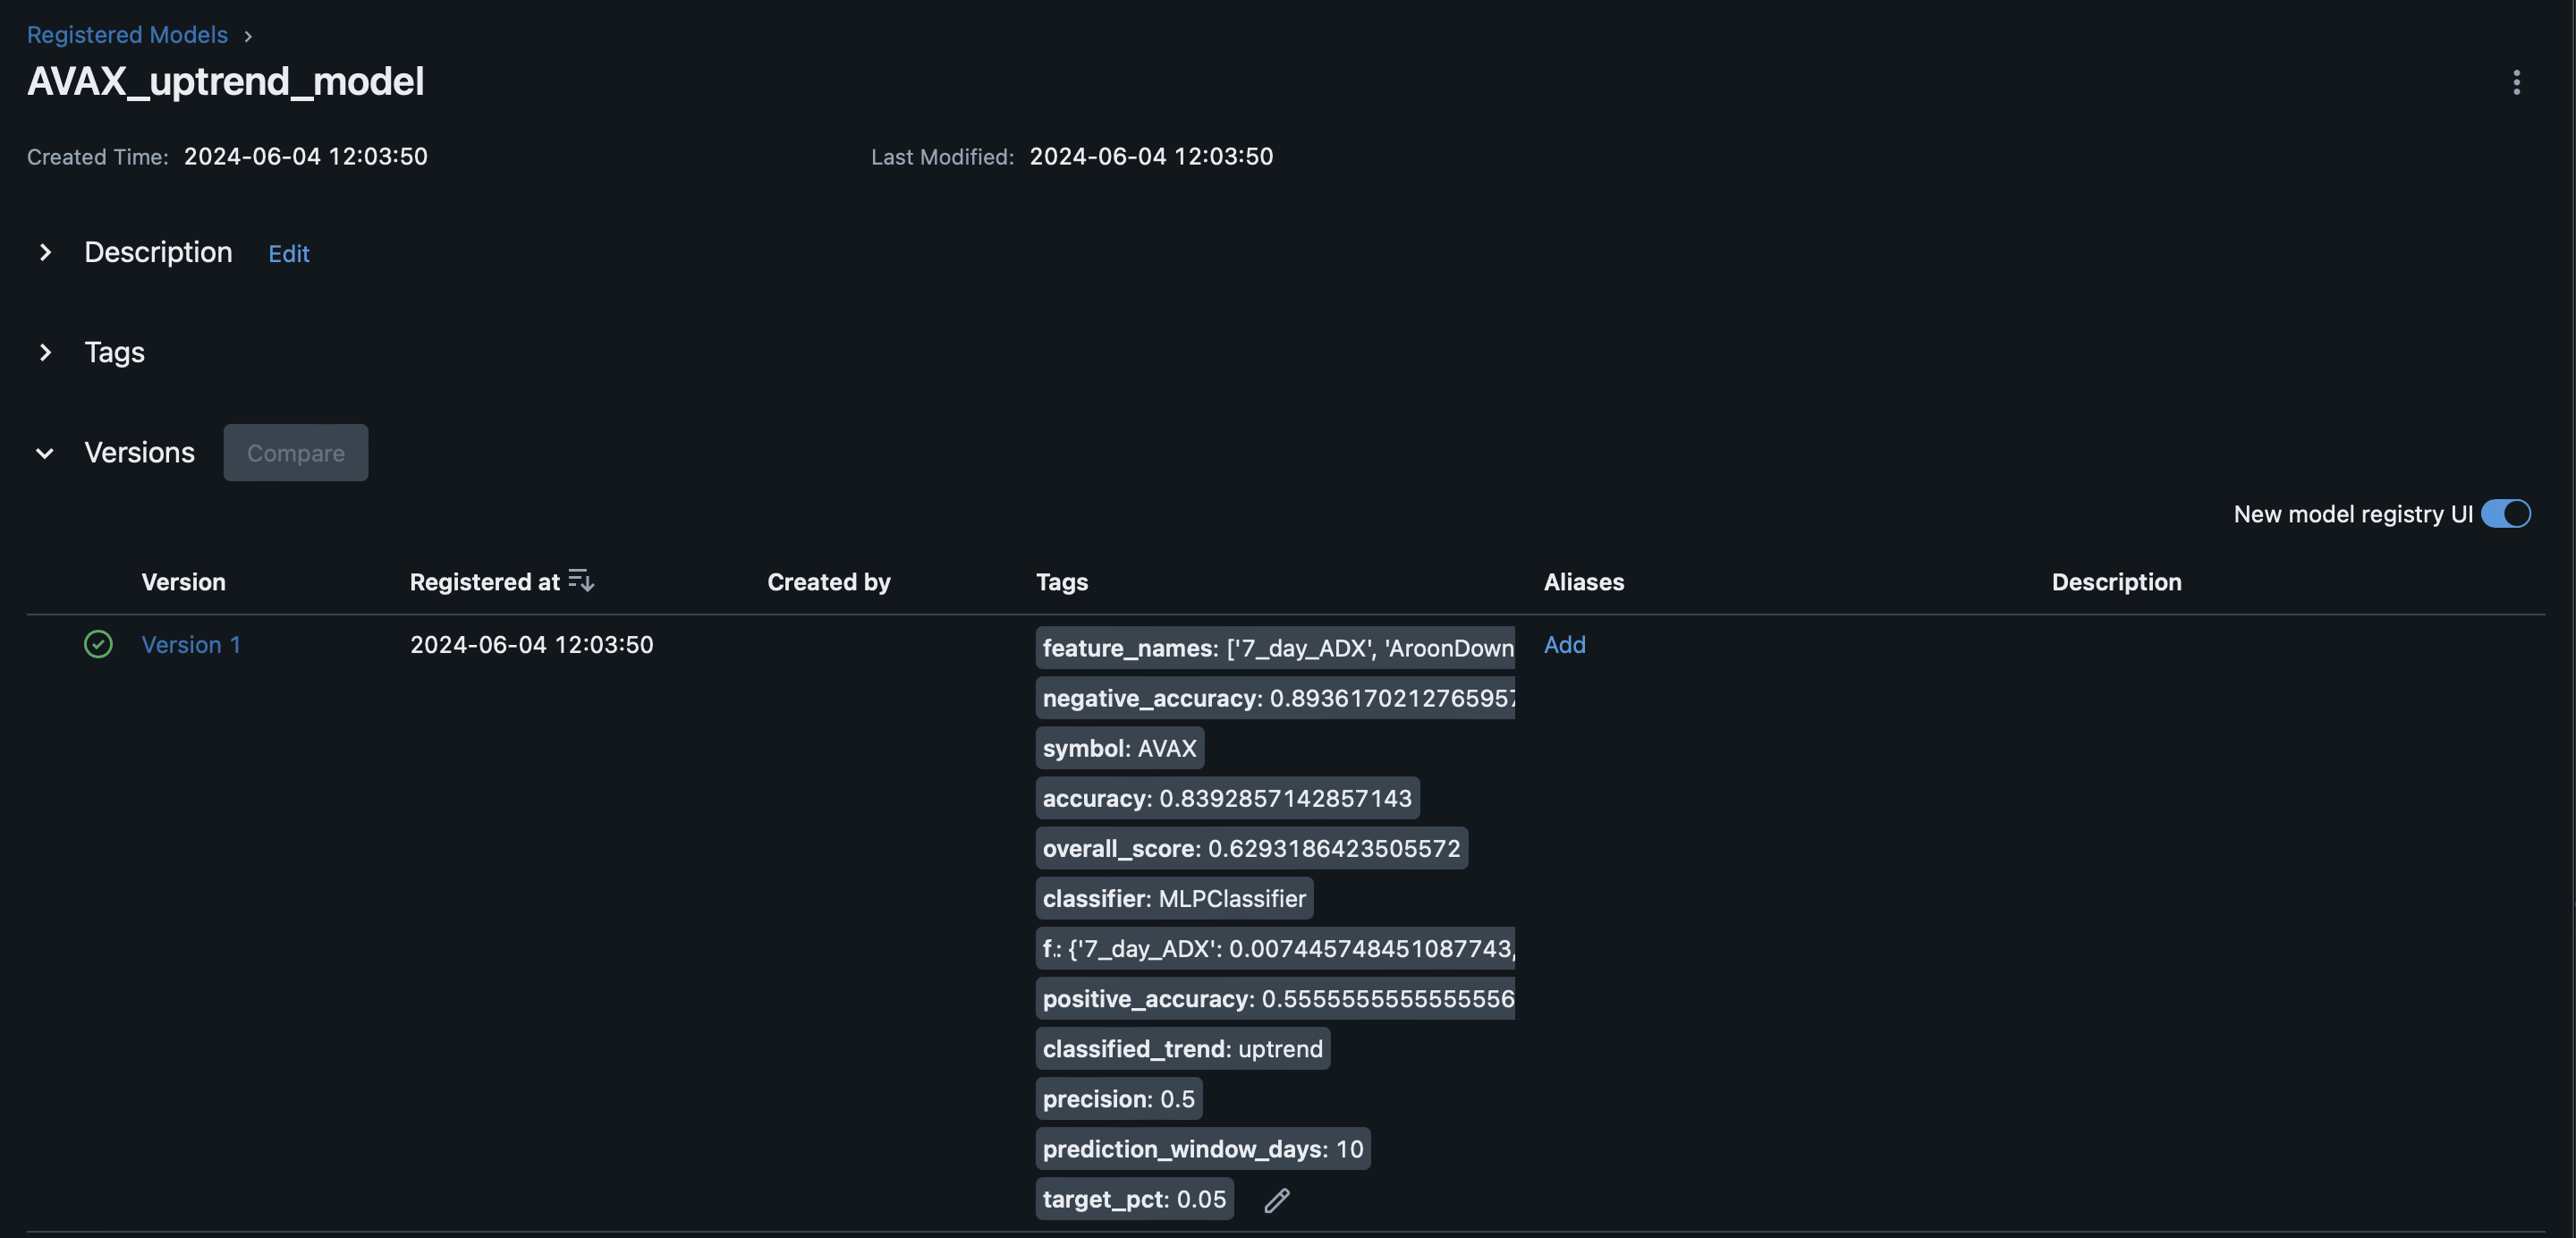
Model Registry
By going on the models section we can see the models that are stored in Model Registry
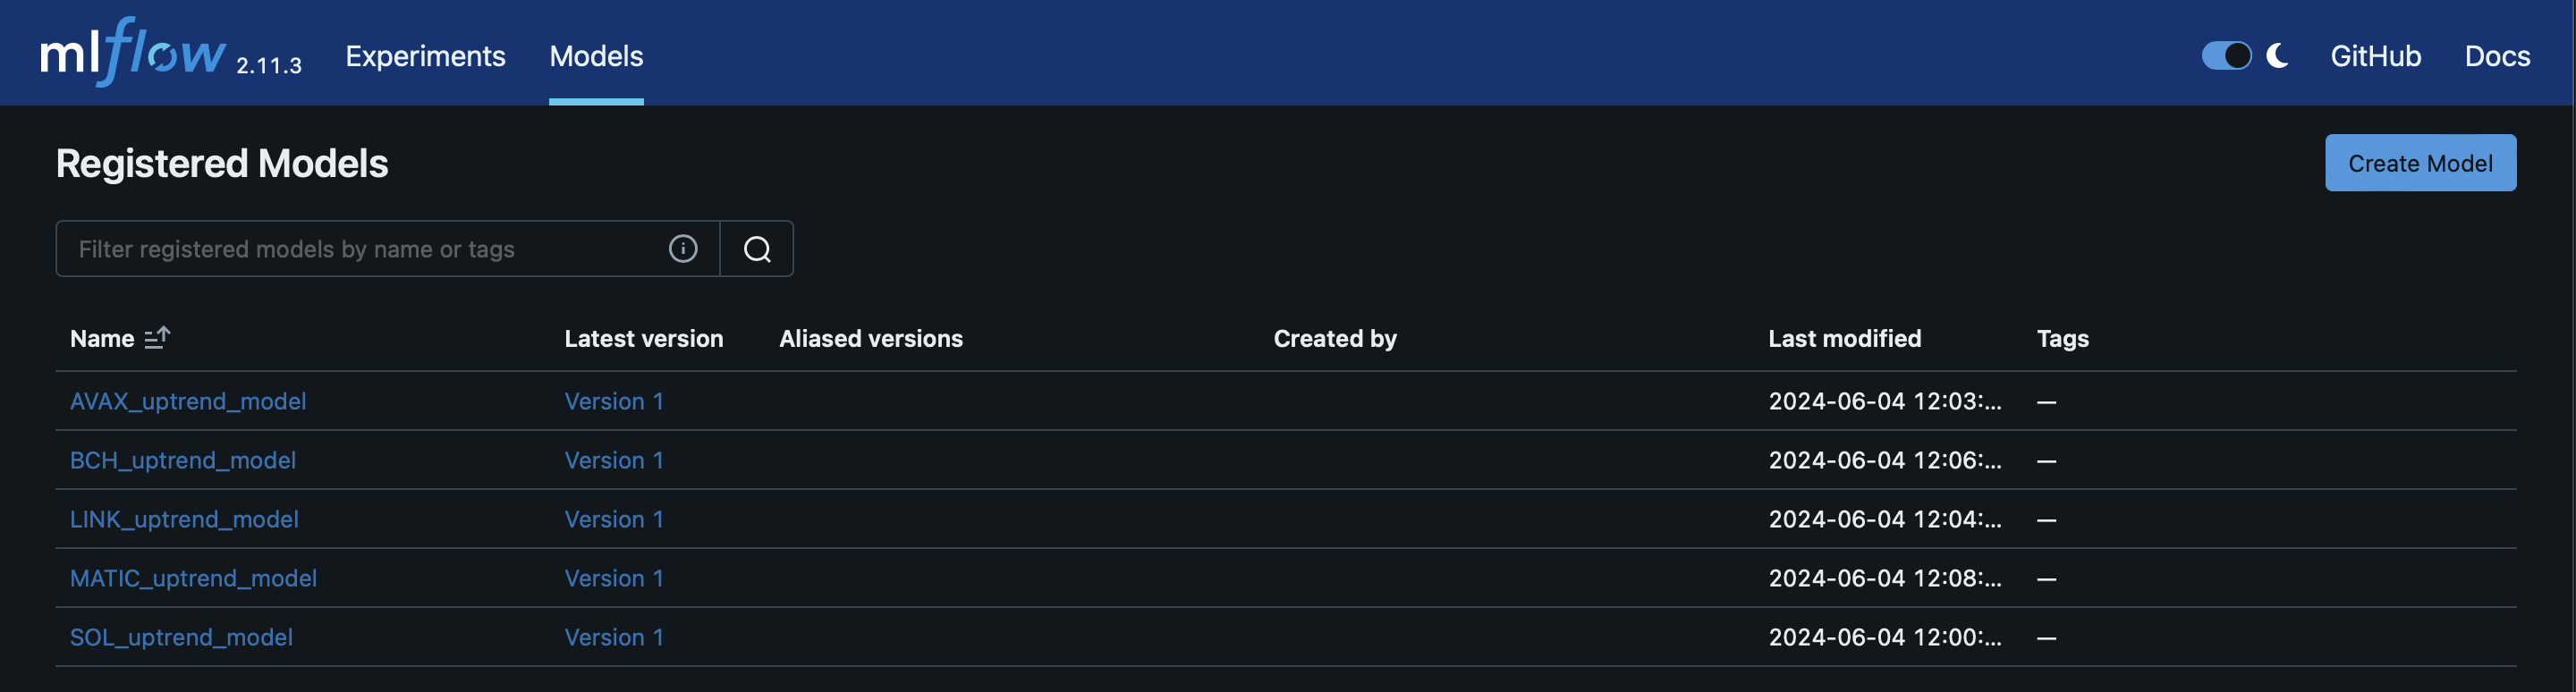
By choosing one of them we can we get all the information we stored about the model
Running batch predictions
Now that we have some models deployed we can get predictions, to do that we create a script that takes as command line argument the trend type
import warnings
import sys

from deployment.deployment_pipeline import TrendType
from predictions.batch_predict import BatchPredictions

# Filter out the specific warning
warnings.filterwarnings("ignore", category=UserWarning)

if __name__ == "__main__":
    trend_type = TrendType(sys.argv[1])

    predictions = BatchPredictions(trend_type).run()

    for prediction in predictions:
        print(prediction)
        print('--------------------------')
python -m predictions.batch_predictions uptrend
Prediction(symbol='AVAX', prediction=0.08797024112491493, tags=ModelTags(positive_accuracy='0.5555555555555556', negative_accuracy='0.8936170212765957', overall_score='0.6293186423505572', accuracy='0.8392857142857143', precision='0.5', symbol='AVAX', classifier='MLPClassifier', classified_trend='uptrend', target_pct='0.05', prediction_window_days='10', feature_names="['7_day_ADX', 'AroonDown', 'AroonUp', 'MACD', 'MACD_Signal', 'MACD_Hist', '7_day_RSI', 'SlowK', 'SlowD', '7_day_MFI', '7_day_DX', '7_day_TRIX', 'PPO', 'OBV_pct_change', 'AD_pct_change', 'BBANDS_distance_pct', '2_day_SMA_10_day_SMA_pct_diff', '2_day_SMA_20_day_SMA_pct_diff', '10_day_SMA_20_day_SMA_pct_diff']", feature_importance="{'7_day_ADX': 0.007445748451087743, 'AroonDown': -0.03420282474310941, 'AroonUp': -0.006806365934893178, 'MACD': 0.009851930090292742, 'MACD_Signal': 0.01872037634072151, 'MACD_Hist': -0.00038134231684378337, '7_day_RSI': -0.00447165026146559, 'SlowK': 0.0057498121581468515, 'SlowD': -0.012869322604550324, '7_day_MFI': 0.01109616869923093, '7_day_DX': 0.008746157567726159, '7_day_TRIX': -0.09396269471943668, 'PPO': -0.022627486901161814, 'OBV_pct_change': -0.006502963995860393, 'AD_pct_change': -0.007990124555058938, 'BBANDS_distance_pct': 0.005792011465134371, '2_day_SMA_10_day_SMA_pct_diff': -0.037850639901746794, '2_day_SMA_20_day_SMA_pct_diff': 0.0754213434764908, '10_day_SMA_20_day_SMA_pct_diff': 0.04341329625672436}"))
--------------------------
Prediction(symbol='BCH', prediction=0.5242774257331716, tags=ModelTags(positive_accuracy='0.6428571428571429', negative_accuracy='0.9545454545454546', overall_score='0.7989699955217198', accuracy='0.8793103448275862', precision='0.8181818181818182', symbol='BCH', classifier='MLPClassifier', classified_trend='uptrend', target_pct='0.05', prediction_window_days='10', feature_names="['7_day_ADX', 'AroonDown', 'AroonUp', 'MACD', 'MACD_Signal', 'MACD_Hist', '7_day_RSI', 'SlowK', 'SlowD', '7_day_MFI', '7_day_DX', '7_day_TRIX', 'PPO', 'OBV_pct_change', 'AD_pct_change', 'BBANDS_distance_pct', '2_day_SMA_10_day_SMA_pct_diff', '2_day_SMA_20_day_SMA_pct_diff', '10_day_SMA_20_day_SMA_pct_diff']", feature_importance="{'7_day_ADX': -0.011434522711156974, 'AroonDown': 0.0034590618165668933, 'AroonUp': 0.00036602358400324565, 'MACD': -0.0019961766024331968, 'MACD_Signal': -0.0402090192861234, 'MACD_Hist': -0.020724063948034027, '7_day_RSI': -0.0012447167585948715, 'SlowK': 0.0013838787305832333, 'SlowD': 0.003059973207332214, '7_day_MFI': -0.006375397144073281, '7_day_DX': 0.002475381276557034, '7_day_TRIX': 0.018376494677847424, 'PPO': -0.010871152759239108, 'OBV_pct_change': 0.0017858697031143515, 'AD_pct_change': 0.00032245040005649174, 'BBANDS_distance_pct': -0.015327945788925624, '2_day_SMA_10_day_SMA_pct_diff': 0.009938639667201942, '2_day_SMA_20_day_SMA_pct_diff': 0.005847329537153156, '10_day_SMA_20_day_SMA_pct_diff': 0.02582306481195758}"))
--------------------------
Prediction(symbol='GRT', prediction=0, tags=ModelTags(positive_accuracy='0.8095238095238095', negative_accuracy='0.7777777777777778', overall_score='0.7493600668337511', accuracy='0.7894736842105263', precision='0.68', symbol='GRT', classifier='RidgeClassifier', classified_trend='uptrend', target_pct='0.05', prediction_window_days='10', feature_names="['7_day_ADX', 'AroonDown', 'AroonUp', 'MACD', 'MACD_Signal', 'MACD_Hist', '7_day_RSI', 'SlowK', 'SlowD', '7_day_MFI', '7_day_DX', '7_day_TRIX', 'PPO', 'OBV_pct_change', 'AD_pct_change', 'BBANDS_distance_pct', '2_day_SMA_10_day_SMA_pct_diff', '2_day_SMA_20_day_SMA_pct_diff', '10_day_SMA_20_day_SMA_pct_diff']", feature_importance="{'7_day_ADX': -0.004653367573063757, 'AroonDown': 0.00543810871267663, 'AroonUp': 0.01081495407838227, 'MACD': -0.00043034328831368453, 'MACD_Signal': 0.0007199178505146046, 'MACD_Hist': 6.171883375290897e-05, '7_day_RSI': 0.021678857731158806, 'SlowK': 0.025011955969490348, 'SlowD': -0.008690773448199672, '7_day_MFI': -0.006178877454886704, '7_day_DX': 0.0023309299936438866, '7_day_TRIX': -0.015204482187342777, 'PPO': 0.04873721704289985, 'OBV_pct_change': 0.00015699279263542158, 'AD_pct_change': -8.033011573586306e-05, 'BBANDS_distance_pct': -0.00245956447445686, '2_day_SMA_10_day_SMA_pct_diff': 0.003682598406320119, '2_day_SMA_20_day_SMA_pct_diff': 0.0029241021973484007, '10_day_SMA_20_day_SMA_pct_diff': 0.014736876161246266}"))
--------------------------
Getting predictions from the web service
First we have to spin up the fast api web service
uvicorn api.main:app
INFO:     Started server process [3407]
INFO:     Waiting for application startup.
INFO:     Application startup complete.
INFO:     Uvicorn running on http://127.0.0.1:8000 (Press CTRL+C to quit)
First we make a request to get the available models
curl -X 'GET' \
  'http://127.0.0.1:8000/models' \
  -H 'accept: application/json'
And the reponse we get
[
  {
    "symbol": "AAVE",
    "trend_type": "uptrend",
    "feature_importance": {
      "7_day_ADX": -0.00797688883261002,
      "AroonDown": -0.0022145703244972445,
      "AroonUp": -0.019396860838998106,
      "MACD": 0.0020402320649134742,
      "MACD_Signal": 0.0013625120958178946,
      "MACD_Hist": -0.00046911929490799515,
      "7_day_RSI": -0.02801970294924038,
      "SlowK": -0.005147482905781799,
      "SlowD": -0.0008999146193456065,
      "7_day_MFI": -0.0002451013774450789,
      "7_day_DX": -0.0038788266259655287,
      "7_day_TRIX": -0.054302946886459556,
      "PPO": 0.0040880260641255875,
      "OBV_pct_change": 0.002526268853129514,
      "AD_pct_change": -0.0025933136757249984,
      "BBANDS_distance_pct": 0.000040658247198773904,
      "2_day_SMA_10_day_SMA_pct_diff": -0.0023438896462991995,
      "2_day_SMA_20_day_SMA_pct_diff": -0.00707757311791206,
      "10_day_SMA_20_day_SMA_pct_diff": -0.00014667864379082877
    },
    "performance_metrics": {
      "positive_accuracy": 0.5833333333333334,
      "negative_accuracy": 0.9347826086956522,
      "overall_score": 0.7281634182908546,
      "accuracy": 0.8620689655172413,
      "precision": 0.7
    },
    "target_pct": 0.05,
    "prediction_window_days": 10
  },
  {
    "symbol": "AVAX",
    "trend_type": "uptrend",
    "feature_importance": {
      "7_day_ADX": 0.007445748451087743,
      "AroonDown": -0.03420282474310941,
      "AroonUp": -0.006806365934893178,
      "MACD": 0.009851930090292742,
      "MACD_Signal": 0.01872037634072151,
      "MACD_Hist": -0.00038134231684378337,
      "7_day_RSI": -0.00447165026146559,
      "SlowK": 0.0057498121581468515,
      "SlowD": -0.012869322604550324,
      "7_day_MFI": 0.01109616869923093,
      "7_day_DX": 0.008746157567726159,
      "7_day_TRIX": -0.09396269471943668,
      "PPO": -0.022627486901161814,
      "OBV_pct_change": -0.006502963995860393,
      "AD_pct_change": -0.007990124555058938,
      "BBANDS_distance_pct": 0.005792011465134371,
      "2_day_SMA_10_day_SMA_pct_diff": -0.037850639901746794,
      "2_day_SMA_20_day_SMA_pct_diff": 0.0754213434764908,
      "10_day_SMA_20_day_SMA_pct_diff": 0.04341329625672436
    },
    "performance_metrics": {
      "positive_accuracy": 0.5555555555555556,
      "negative_accuracy": 0.8936170212765957,
      "overall_score": 0.6293186423505572,
      "accuracy": 0.8392857142857143,
      "precision": 0.5
    },
    "target_pct": 0.05,
    "prediction_window_days": 10
  },
  {
    "symbol": "SOL",
    "trend_type": "uptrend",
    "feature_importance": {
      "7_day_ADX": 0.015000153306740257,
      "AroonDown": 0.02451770026337218,
      "AroonUp": 0.03236303460495203,
      "MACD": 0.002078305953432907,
      "MACD_Signal": 0.0029395530612216997,
      "MACD_Hist": -0.000425158534885004,
      "7_day_RSI": -0.0024308885089579656,
      "SlowK": 0.0179528613798285,
      "SlowD": 0.01347377938915217,
      "7_day_MFI": 0.021630318557917718,
      "7_day_DX": 0.010587214295264465,
      "7_day_TRIX": 0.0652940677416978,
      "PPO": 0.003218341366393632,
      "OBV_pct_change": 0.004427564807075552,
      "AD_pct_change": 0.004997725522612719,
      "BBANDS_distance_pct": 0.006859544173414918,
      "2_day_SMA_10_day_SMA_pct_diff": 0.0007349004310821411,
      "2_day_SMA_20_day_SMA_pct_diff": 0.00025054599758185856,
      "10_day_SMA_20_day_SMA_pct_diff": 0.0024395271011933245
    },
    "performance_metrics": {
      "positive_accuracy": 0.8333333333333334,
      "negative_accuracy": 0.6756756756756757,
      "overall_score": 0.6800846300846302,
      "accuracy": 0.7272727272727273,
      "precision": 0.5555555555555556
    },
    "target_pct": 0.05,
    "prediction_window_days": 10
  }
]
And now to get a prediction
curl -X 'GET' \
  'http://127.0.0.1:8000/prediction?symbol=SOL&trend_type=uptrend' \
  -H 'accept: application/json'
And the response
{
  "prediction_probabilities": 0.4,
  "symbol": "SOL",
  "trend_type": "uptrend"
}